ff.sh: A Quiet, Interactive File Finder for macOS

If you’ve ever run sudo find / -name "something" on a modern Mac, you know the result: the match you wanted is buried under hundreds of Operation not permitted lines. macOS protects large parts of the file system (SIP, TCC-protected folders, sealed system volumes), and find prints an error for every one of them. Even as root, you get the noise.

ff.sh is a small bash script that fixes this. It searches the file system for a filename or pattern, hides the permission errors, and lets you browse the results in a full-screen terminal interface.

How it works

1. Quiet searching. The script runs find with stderr discarded, so only real matches are kept. It also skips /System/Volumes. On modern macOS the Data volume is firmlinked into /, so searching both would list every file twice. /dev and /proc are skipped as well.

2. Progress feedback. A full-disk search can take a while. The search runs in the background while a spinner and a live match count update in your terminal, so you can tell it’s still working.

3. Results collected into arrays. When the search finishes, the matches are sorted and grouped by folder into bash arrays. Nothing is printed line by line.

4. A full-screen browser. The script switches to the terminal’s alternate screen. The top half lists every folder that contains a match, with a count. The bottom half lists the matching items in the highlighted folder and updates as you move through the folders.

Press Esc and the full-screen view disappears. You’re back at your prompt with your scrollback untouched.

Installing it

Save the script below as ff.sh, then make it executable. You only need to do this once:

chmod +x ff.sh

Optionally, move it somewhere on your PATH so you can run it from anywhere:

sudo mv ff.sh /usr/local/bin/ff
#!/usr/bin/env bash
# ff.sh - search the file system for a filename or pattern and browse the results.
#
# Usage:  sudo ./ff.sh [-x]  [start-dir]
#
#   sudo ./ff.sh hosts                 # anything with "hosts" in the name, searched from /
#   sudo ./ff.sh '*.plist' /Library    # glob pattern, searched under /Library
#   sudo ./ff.sh -x hosts              # exact filename match only
#
# While searching, a spinner and running match count are shown. When the search
# finishes, a full-screen browser opens:
#   top half     folders that contain matches
#   bottom half  matching items in the highlighted folder
#
# Keys:  Up/Down (or k/j)  move        PgUp/PgDn  page        Home/End  first/last
#        Tab               switch between the folder pane and the file pane
#        Esc (or q)        leave full screen and return to the console
#
# Matching is case-insensitive. A pattern with no wildcard (* ? [ ]) is treated
# as a substring match unless -x is given. Permission errors are hidden.
#
# Works with the stock macOS bash 3.2.
 
exact=0
if [ "$1" = "-x" ]; then
    exact=1
    shift
fi
 
if [ -z "$1" ]; then
    echo "Usage: sudo $0 [-x]  [start-dir]" >&2
    exit 1
fi
 
pattern="$1"
start="${2:-/}"
 
if [ ! -d "$start" ]; then
    echo "Start directory not found: $start" >&2
    exit 1
fi
 
if [ "$(id -u)" -ne 0 ]; then
    echo "Note: not running as root; some locations will be skipped. Use: sudo $0 ..." >&2
fi
 
# Wrap plain text in wildcards unless -x was given or the user supplied a glob.
glob="$pattern"
if [ "$exact" -eq 0 ]; then
    case "$glob" in
        *[\*\?\[]*) ;;
        *) glob="*${glob}*" ;;
    esac
fi
 
# /System/Volumes/Data is firmlinked into / on modern macOS; skipping it avoids
# listing every file twice. /dev and /proc are pointless to search.
run_find() {
    find "$start" \
        \( -path /System/Volumes -o -path /dev -o -path /proc \) -prune \
        -o -iname "$glob" -print 2>/dev/null
}
 
# If output is piped or redirected, behave like a plain quiet find.
if [ ! -t 1 ] || [ ! -t 0 ]; then
    run_find
    exit 0
fi
 
tmp=$(mktemp -d "${TMPDIR:-/tmp}/ff.XXXXXX") || exit 1
raw="$tmp/raw"
sorted="$tmp/sorted"
find_pid=""
saved_stty=""
tui_on=0
 
cleanup() {
    if [ -n "$find_pid" ]; then
        kill "$find_pid" 2>/dev/null
    fi
    if [ "$tui_on" -eq 1 ]; then
        printf '\033[0m\033[?25h\033[?1049l'
    else
        printf '\033[?25h' >&2
    fi
    if [ -n "$saved_stty" ]; then
        stty "$saved_stty" 2>/dev/null
    fi
    rm -rf "$tmp"
}
trap cleanup EXIT
trap 'exit 130' INT TERM
 
# ---------------------------------------------------------------- search phase
run_find > "$raw" &
find_pid=$!
 
spin='|/-\'
i=0
printf '\033[?25l' >&2
while kill -0 "$find_pid" 2>/dev/null; do
    n=$(wc -l < "$raw" | tr -d ' ') printf '\r\033[K%s Searching %s for "%s" ... %s found' \ "${spin:$((i % 4)):1}" "$start" "$pattern" "$n" >&2
    i=$((i + 1))
    sleep 0.1
done
wait "$find_pid" 2>/dev/null
find_pid=""
printf '\r\033[K' >&2
 
if [ ! -s "$raw" ]; then
    echo "No matches found for \"$pattern\" under $start" >&2
    exit 0
fi
 
printf 'Organizing %s results...' "$(wc -l < "$raw" | tr -d ' ')" >&2
 
# --------------------------------------------------------------- build arrays
tab=$'\t'
awk '{
    n = match($0, /\/[^\/]*$/)
    if (n == 0)      { d = ".";                   f = $0 }
    else if (n == 1) { d = "/";                   f = substr($0, 2) }
    else             { d = substr($0, 1, n - 1);  f = substr($0, n + 1) }
    print d "\t" f
}' "$raw" | LC_ALL=C sort -t "$tab" -k1,1 -k2,2 > "$sorted"
 
dirs=()      # unique folders
dcount=()    # number of matches in each folder
dstart=()    # index into files[] where each folder's matches begin
files=()     # matching names, grouped by folder
nd=-1
nf=0
last=""
while IFS="$tab" read -r d f; do
    if [ "$nd" -lt 0 ] || [ "$d" != "$last" ]; then
        nd=$((nd + 1))
        dirs[$nd]="$d"
        dstart[$nd]=$nf
        dcount[$nd]=0
        last="$d"
    fi
    files[$nf]="$f"
    nf=$((nf + 1))
    dcount[$nd]=$((dcount[$nd] + 1))
done < "$sorted" ndirs=$((nd + 1)) printf '\r\033[K' >&2
 
# ------------------------------------------------------------------------ TUI
sel=0        # selected folder
top_off=0    # first visible folder
fsel=0       # selected file within the folder
f_off=0      # first visible file within the folder
focus=0      # 0 = folder pane, 1 = file pane
T=10
B=10
 
draw() {
    local rows cols r idx s t mark i fcount path
    read -r rows cols < <(stty size </dev/tty 2>/dev/null)
    [ -z "$rows" ] && rows=24
    [ -z "$cols" ] && cols=80
 
    T=$(( (rows - 3) / 2 ))
    [ "$T" -lt 1 ] && T=1
    B=$(( rows - T - 2 ))
    [ "$B" -lt 1 ] && B=1
 
    fcount=${dcount[$sel]}
    path=${dirs[$sel]}
 
    # keep selections inside their scroll windows
    [ "$sel" -lt "$top_off" ] && top_off=$sel
    [ "$sel" -ge $((top_off + T)) ] && top_off=$((sel - T + 1))
    [ "$fsel" -lt "$f_off" ] && f_off=$fsel
    [ "$fsel" -ge $((f_off + B)) ] && f_off=$((fsel - B + 1))
 
    local buf=""
 
    # header (row 1)
    s=" ff \"$pattern\" | $nf items in $ndirs folders | folder $((sel + 1))/$ndirs | Tab: switch pane  PgUp/PgDn  Esc: exit"
    printf -v t '%-*.*s' "$cols" "$cols" "$s"
    buf="$buf"$'\033[1;1H\033[0m\033[7m'"$t"$'\033[0m'
 
    # folder pane (rows 2 .. T+1)
    for ((i = 0; i < T; i++)); do r=$((i + 2)) idx=$((top_off + i)) buf="$buf"$'\033['"$r"$';1H\033[K' if [ "$idx" -lt "$ndirs" ]; then if [ "$idx" -eq "$sel" ]; then mark="> "; else mark="  "; fi
            printf -v s '%s%5d  %s' "$mark" "${dcount[$idx]}" "${dirs[$idx]}"
            printf -v t '%-*.*s' "$cols" "$cols" "$s"
            if [ "$idx" -eq "$sel" ]; then
                if [ "$focus" -eq 0 ]; then
                    buf="$buf"$'\033[7m'"$t"$'\033[0m'
                else
                    buf="$buf"$'\033[1m'"$t"$'\033[0m'
                fi
            else
                buf="$buf${s:0:$cols}"
            fi
        fi
    done
 
    # separator (row T+2)
    r=$((T + 2))
    if [ "$focus" -eq 0 ]; then t="folders"; else t="files"; fi
    s="--- [$t focus] $fcount in $path "
    local fill=$((cols - ${#s}))
    if [ "$fill" -gt 0 ]; then
        printf -v t '%*s' "$fill" ''
        s="$s${t// /-}"
    fi
    printf -v t '%-*.*s' "$cols" "$cols" "$s"
    buf="$buf"$'\033['"$r"$';1H\033[K\033[1m'"$t"$'\033[0m'
 
    # file pane (rows T+3 .. rows)
    for ((i = 0; i < B; i++)); do
        r=$((T + 3 + i))
        idx=$((f_off + i))
        buf="$buf"$'\033['"$r"$';1H\033[K'
        if [ "$idx" -lt "$fcount" ]; then
            s="  ${files[$((dstart[sel] + idx))]}"
            if [ "$idx" -eq "$fsel" ] && [ "$focus" -eq 1 ]; then
                printf -v t '%-*.*s' "$cols" "$cols" "$s"
                buf="$buf"$'\033[7m'"$t"$'\033[0m'
            else
                buf="$buf${s:0:$cols}"
            fi
        fi
    done
 
    printf '%s' "$buf"
}
 
move() {
    local d=$1 n c
    if [ "$focus" -eq 0 ]; then
        n=$((sel + d))
        [ "$n" -lt 0 ] && n=0
        [ "$n" -ge "$ndirs" ] && n=$((ndirs - 1))
        if [ "$n" -ne "$sel" ]; then
            sel=$n
            fsel=0
            f_off=0
        fi
    else
        c=${dcount[$sel]}
        n=$((fsel + d))
        [ "$n" -lt 0 ] && n=0
        [ "$n" -ge "$c" ] && n=$((c - 1))
        fsel=$n
    fi
}
 
page() {
    # $1 = direction (+1/-1)
    if [ "$focus" -eq 0 ]; then move $(($1 * T)); else move $(($1 * B)); fi
}
 
# Read the remainder of an escape sequence. A short tty timeout lets us tell a
# bare Esc key apart from an arrow key without waiting a full second (bash 3.2's
# read -t only takes whole seconds).
read_seq() {
    seq=""
    local c
    stty -icanon min 0 time 1 </dev/tty while [ ${#seq} -lt 5 ]; do c=$(dd bs=1 count=1 2>/dev/null </dev/tty)
        [ -z "$c" ] && break
        seq="$seq$c"
        case "$seq" in
            O) continue ;;
            \[*[A-Za-z~] | O?) break ;;
        esac
    done
    stty -icanon min 1 time 0 </dev/tty
}
 
saved_stty=$(stty -g)
stty -echo -icanon min 1 time 0
tui_on=1
printf '\033[?1049h\033[?25l\033[2J'
 
while true; do
    draw
    key=""
    IFS= read -rsn1 key </dev/tty || break
    case "$key" in
        $'\033')
            read_seq
            case "$seq" in
                "")               break ;;
                '[A' | OA)        move -1 ;;
                '[B' | OB)        move 1 ;;
                '[5~')            page -1 ;;
                '[6~')            page 1 ;;
                '[H' | '[1~' | OH) move -1000000000 ;;
                '[F' | '[4~' | OF) move 1000000000 ;;
            esac
            ;;
        q | Q) break ;;
        k)     move -1 ;;
        j)     move 1 ;;
        $'\t') focus=$((1 - focus)) ;;
    esac
done
 
exit 0

.
Escape & as &amp; and < as &lt; and > as &gt; inside the code block, or use a code-block in the visual editor instead. –>

Usage

sudo ./ff.sh hosts                 # any name containing "hosts", searched from /
sudo ./ff.sh '*.plist' /Library    # glob pattern, limited to /Library
sudo ./ff.sh -x hosts              # exact filename match only

Matching is case-insensitive. Plain text with no wildcards is treated as a substring match, and -x turns that off.

Controls

Key Action
↑ / ↓ (or k / j) Move the selection
PgUp / PgDn Move a page at a time
Home / End Jump to the first or last item
Tab Switch between the folder pane and the file pane
Esc (or q) Exit and return to the console

Implementation notes

A few details may interest other script writers:

  • It runs on the stock macOS bash 3.2. That rules out associative arrays, mapfile and fractional read -t timeouts. Folders and files are tracked with parallel indexed arrays, and a sort pass groups the matches by folder so each folder can be a slice of one array.
  • Esc is told apart from arrow keys without lag. Arrow keys send escape sequences that start with the same byte as the Esc key. Bash 3.2’s read -t only accepts whole seconds, which would make Esc wait a full second. Instead, the script briefly sets the terminal to min 0 time 1 and reads the rest of the sequence with dd. A bare Esc is recognized in about 0.1 seconds.
  • The screen is drawn in one write. Each redraw is built into a single string with ANSI cursor-positioning codes and printed once, which avoids flicker.
  • Cleanup is handled by a trap. An EXIT trap restores the terminal, cursor and screen mode and deletes the temp files, even after Ctrl-C.
  • Piping still works. If stdout isn’t a terminal, for example sudo ./ff.sh foo | grep bar, the script skips the interface and prints a plain quiet list.

A note on Full Disk Access

Even with sudo, macOS can block some locations, such as Mail or Photos data, unless your terminal app has Full Disk Access (System Settings → Privacy & Security → Full Disk Access). The script hides those errors, so if a file you expect is missing, check that setting.

And just in case you were wondering, the text above was created by AI as was the script. But it works amazingly well, give it a chance if you have the need.
Generating a MAP.md file

Here is the prompt that I use to generate MAP.md files in my projects.


Explore this codebase and create a MAP.md document that is designed to be used by Claude in the future as a guide as to what’s where, how it works, and what it does. This includes configuration, data access, architectural style, test location and testing style, frameworks used, languages used, GitHub configuration, custom skills and agents and commands, git branching style, and anything else that future you will need to know so you don’t explore the entire codebase when I want to do something.

Update or create a CLAUDE.md as well with the basics of the application, that states that MAP.md is the "living project document" that is to be updated whenever things change. The user should be prompted to update MAP.md any time the project is altered.


This prompt comes courtesy of Rob Conery. I recommend you check his stuff out.

Search SQL Server triggers, functions, and stored procedures for text

As kind of a follow up to Search SQL Server database triggers for table name, I needed to search for some text that was used to throw an exception in my SQL Server database, but it has grown so large that I did not want to try to spelunk through each and every trigger, function, and stored procedure.

Luckily, in much the same way as the above post, you can query the sys.sql_modules table and find this in one shot. Here is how that looks, where you will of course fill in your text for “SEARCH TEXT HERE”:

SELECT 
    OBJECT_SCHEMA_NAME(module.object_id) AS SchemaName,
    OBJECT_NAME(module.object_id) AS ObjectName,
    object.type_desc AS ObjectType
FROM sys.sql_modules AS module
    JOIN sys.objects AS object ON module.object_id = object.object_id
WHERE module.definition LIKE '%SEARCH TEXT HERE%'
ORDER BY SchemaName, ObjectName

BTW, today is the sad 10th Anniversary of the passing of Hollywood icon Leonard Nimoy, stage and screen actor and director extraordinaire known mostly for his recurring roles in Mission: Impossible and Fringe. And there was some other TV show that he was on as well I think.

Download Azure blobs to local storage and delete via Powershell

I have years and years worth of Azure blobs that are just sitting there taking up space and costing me money, and I wanted to save some money but still keep the files around just on the one-in-a-million chance that I might need one of them in the future. True, this will not save me much money, but who cares? Because software engineering…

Windows PowerShell to the rescue!

I wrote up a script to hook into my storage account and download the files to a local directory of my choosing, and then delete the file if the download is successful.

I would recommend using the latest 7.5 version of PowerShell for this process. In addition, you may need to have the Azure tools installed, which would involve running this command:

Install-Module -Name Az -AllowClobber -Scope CurrentUser

Then you need to authenticate with Azure, which would mean running this command:

Connect-AzAccount

Depending on the configuration of your Azure account, you may need to provide a tenant ID on the command line to connect up to your Azure account, it will alert you if you need to do this. This would look like this, where you would provide your tenant ID in place of the all zeros GUID below:

Connect-AzAccount -TenantId 00000000-0000-0000-0000-000000000000

Here is the script that I am using:

# Change these values for your needs
$resourceGroupName = "resourcegroup"  # change
$storageAccountName = "accountname"  # change
$containerName = "containername"  # change
$localDownloadPath = "C:\Downloads"  # change
$startDate = [datetime]"2019-01-01T00:00:00Z"  # change
$endDate = [datetime]"2019-12-31T23:59:59Z"  # change
 
$storageAccountKey = (Get-AzStorageAccountKey -ResourceGroupName $resourceGroupName -Name $storageAccountName)[0].Value
$ctx = New-AzStorageContext -StorageAccountName $storageAccountName -StorageAccountKey $storageAccountKey
$blobs = Get-AzStorageBlob -Container $containerName -Context $ctx
$filteredBlobs = $blobs | Where-Object { $_.LastModified -ge $startDate -and $_.LastModified -le $endDate } | Select-Object -First 500  # change
foreach ($blob in $filteredBlobs) {
    $blobName = $blob.Name
    $localFilePath = Join-Path -Path $localDownloadPath -ChildPath $blobName
    Write-Host "Downloading $blobName (Last Modified: $($blob.LastModified))..."
    Get-AzStorageBlobContent -Container $containerName -Blob $blobName -Destination $localFilePath -Context $ctx -Force
    if (Test-Path $localFilePath) {
        Write-Host "Deleting $blobName from Azure Storage..."
        Remove-AzStorageBlob -Container $containerName -Blob $blobName -Context $ctx
    } else {
        Write-Host "Error: File $blobName was not downloaded successfully. Skipping deletion."
    }
}
 
Write-Host "Process completed."

You will need to change the variables marked with # change in the first section of this form, and then also modify the limit of 500 in the $filteredBlobs line if you want to do more or less files at one time.

BTW, Happy Independence Day to all my readers in Saint Lucia.

SQL Server GROUP BY query does not consider case-sensitivity of data

The collation on my production SQL Server database unfortunately does not show me case-sensitive values when I do a group by, which is kind of inconvenient when your code is doing string matching.

In order to see this kind of differences, you have to introduce COLLATE entry like this example, where Items is the table name and Category is the column name of the NVARCHAR field that I want to do the case-sensitive group on:

SELECT Category COLLATE SQL_Latin1_General_CP1_CS_AS, COUNT(Category) 
FROM Items 
GROUP BY Category COLLATE SQL_Latin1_General_CP1_CS_AS

iPhone sync hangs on “Syncing (Step 2 of 4) — Preparing to sync”

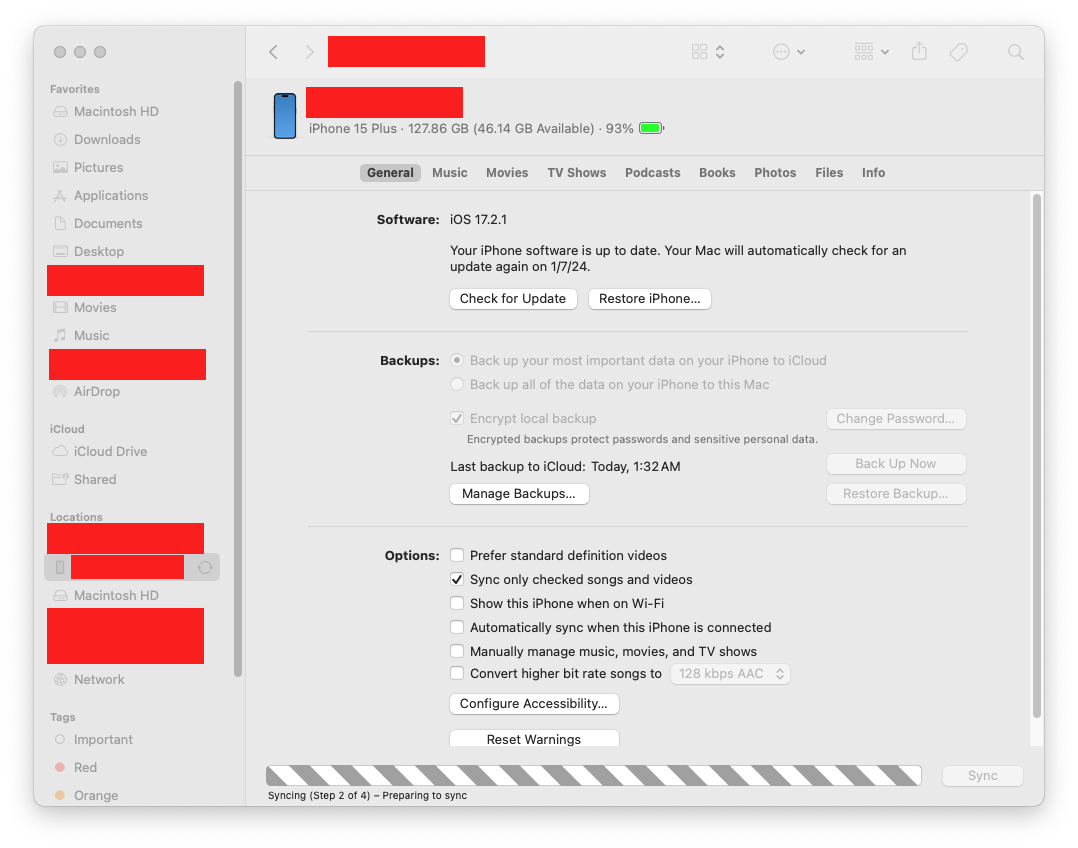
If you are like me (and you know you are), I like to regularly sync my iPhone to my MacBook Pro. This is mainly just for tracking what music I listen to, as I do not do backups to my local computer any more.

Alas, there is a fly in the ointment. Lately I have been plugging my iPhone into my MBP, and then from Finder I click on the iPhone on the left and click the Sync button, and along the bottom it stays at “Syncing (Step 2 of 4) — Preparing to sync” and never moves. Here is an example of what it looks like: (You’ll forgive me if I redact some of the more sensitive bits here.)

By the way, this is an Apple Silicon MBP and it is on the latest Sonoma.

I have a solution that seems to work for me, but keep in mind that your mileage may vary, especially since the workaround that I am talking about involves terminating a system process.

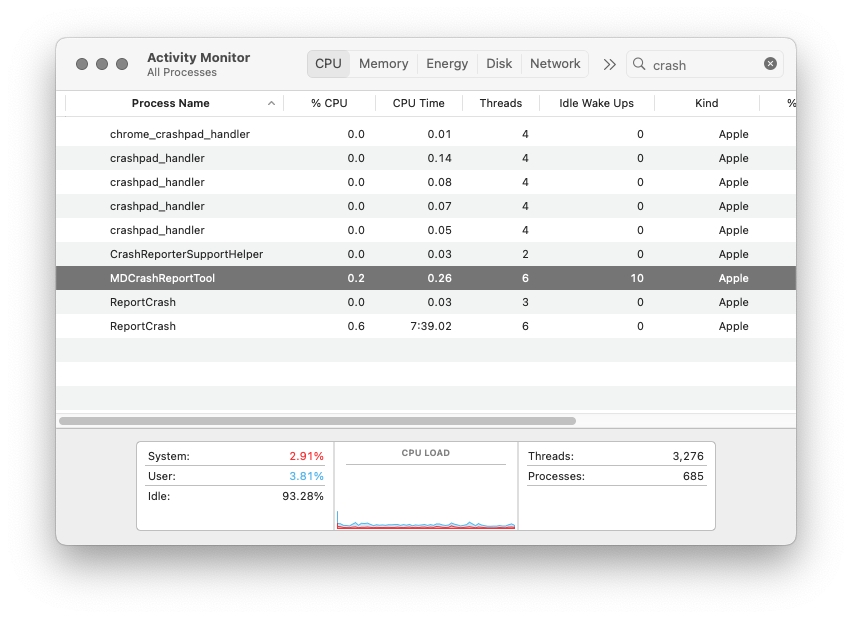
So as it turns out, there is a system process running called “MDCrashReportTool” that is somehow interfering with this process. The way that I have been able to get this to complete is to launch the Activity Monitor, then from the CPU tab search for “crash”, and your window will then look something like this:

Double click on the MDCrashReportTool entry, and from the dialog that pops up click Quit, and then click Force Quit. Once you do this, your sync should go through without incident, even if it was hung on step 2 of 4 when you kill the MDCrashReportTool process.

You will have to do this every time you reboot the computer, as the MDCrashReportTool seems to reappear again for me.

All schemes missing from Xcode when loading old project

There is no worse feeling in the world than when you load up an old Objective-C project that you have to make some changes on, and all of a sudden there are no schemes present for the project when you pull it up in Xcode. As such, there is no way to run the project to see if your changes are good or not.

I did find a solution to this issue. Apparently you need to have Xcode rebuild some of your user data to get the schemes back again.

If this is happening to you when you load your project or workspace into Xcode, do the following steps:

  1. With the project/workspace open in Xcode, right click on the project item all the way at the top of the Project navigator, and select “Show in Finder”.
  2. Quit Xcode.
  3. From the Finder window that just opened, right click on the .xcodeproj file for your project and select “Show Package Contents”.
  4. Double click on the xcuserdata folder.
  5. Right click on the folder that begins with your user name and ends with .xcuserdatad and select “Move to Trash”.
  6. If you are using a workspace instead of just a project (such as if you are using Cocoapods), go back 2 steps to the original folder that Xcode loaded and repeat the above 3 steps except starting by right clicking on the .xcworkspace file instead of the .xcodeproj file.
  7. Load your project/workspace again in Xcode, and the schemes should be rebuilt.

By the way, while we are at it, you do have the xcuserdata folder as an entry in your Git ignore file, right?

Hope you are all having a safe and happy holiday season. See you in 2024.

Advent of Code 2023

Well I just finished up the 2023 Advent of Code, and I must say that I must be getting senile or incompetent, because I found the problems to be challenging well above my pay grade.

However, it was fun to try and solve these problems using Swift.

Have a great holiday, everyone.

EDIT: Oh yeah, almost forgot, here is the link to my Github repo for this:

Advent of Code Solution Machine

Search SQL Server database triggers for table name

Did you ever find yourself in a situation where you have a SQL Server database that has grown out of control, and you need to figure out where a call to insert a record into a particular table might be lurking in one of those triggers?

Oh sure, you can go into each table, expand the triggers folder in each table, then crack open each trigger showing and see if what you are looking for is there. For a database of non-trivial size, I would rather look up “tedium” in the dictionary.

Alas, there is a way to quickly screen down the number of places you may have to look for to find what you need. Open up your database and paste this text into the query window, of course replacing SearchText with whatever table name you need to search for:

SELECT so.name, text FROM sysobjects so, syscomments sc
WHERE TYPE = 'TR' AND so.id = sc.id AND text LIKE '%SearchText%'

For example, if you wanted to find any trigger that inserts a record into a table called Customers, you would do this query:

SELECT so.name, text FROM sysobjects so, syscomments sc
WHERE TYPE = 'TR' AND so.id = sc.id AND text LIKE '%insert into Customers%'

Keep in mind that unless you played with the settings or collation of your database, the case of the text in the LIKE statement above should not matter.

MHS 3.5″ LCD screen with Raspberry Pi

I am saving this here just in case the original source of this goes off line.

To download the drivers for Raspbian Buster, do these steps:

sudo rm -rf LCD-show
git clone https://github.com/goodtft/LCD-show.git
chmod -R 755 LCD-show
cd LCD-show/
sudo ./MHS35-show

To rotate the screen, do these steps:

cd LCD-show/
sudo ./rotate.sh 90

EDIT (10/4/2023):
When you set up the Raspberry Pi to use the LCD screen driver, it does disable the onboard HDMI output ports, so if you attach a cable there you will not get any video or audio.
If you want to reset your Raspberry Pi back to using the HDMI output then instead of the attached screen, do these steps:

cd LCD-show/
sudo ./LCD-hdmi